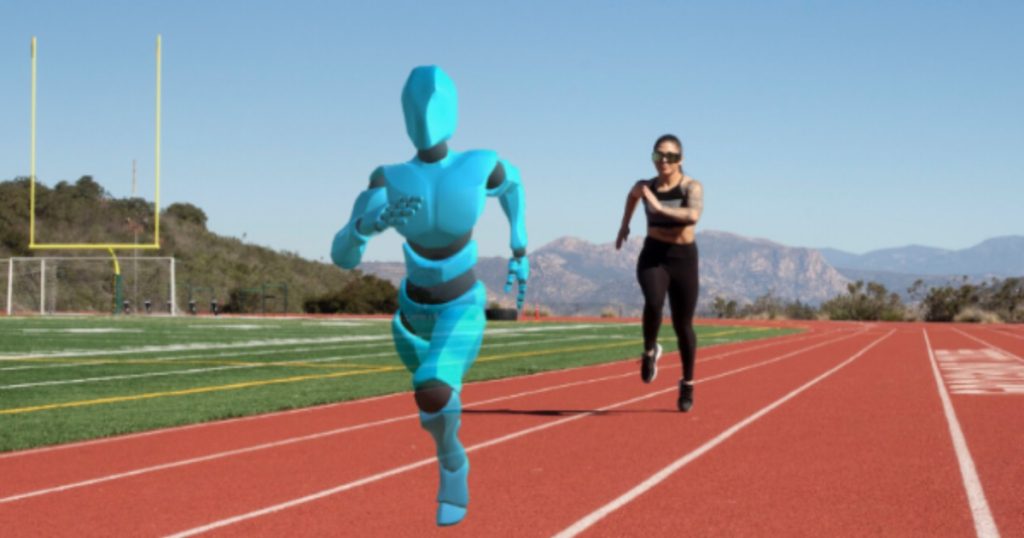
Facebook unveiled its latest machine-learning process called Anticipative Video Transformer (AVT), which is able to predict future actions by using visual interpretation. AVT works as an end-to-end attention-based model for action anticipation in videos. The new model is based on recent breakthroughs in transformer architectures, particularly for natural language processing, and picture modeling for applications ranging from self-driving cars to augmented reality. AVT analyzes an activity to show the potential result specially for AR and the metaverse. Facebook plans for its metaverse apps to work across other platforms and hardware, through APIs that allow programs to talk to each other. Anticipating future activities is a difficult issue for AI since it necessitates both predicting the multimodal distribution of future activities and modelling the course of previous actions. AVT is attention based, so it can process a full sequence in parallel, while recurrent-neural-network-based approaches often forget the past, as they need to process sequences sequentially. AVT also features loss functions that encourage the model to capture the sequential nature of video, which would otherwise be lost by attention-based architectures such as nonlocal networks. AVT consists of two parts: an attention-based backbone (AVT-b) that operates on frames of video and an attention-based…
Read More
Facebook Develops New AI Model that Can Anticipate Future Actions – InfoQ